New - NVIDIA B200 & B300 Dedicated GPU Clusters | Explore GPU clusters
GPU Cloud for Rendering & Transcoding
Power through your most demanding video, audio, and 3D rendering projects with UpCloud’s NVIDIA L4, L40S, H100 & B200 Cloud GPUs.
Designed for studios, creators, and platforms, our service provides the raw GPU power needed for high-resolution rendering and transcoding, combined with a flexible, pay-as-you-go model that saves costs and scales with your project load.
Valeria Dikonova, Product Designer
Pay-as-You-Render Model
Our true hourly billing ensures you only pay for your actual GPU usage. This eliminates waste from idle resources and dramatically reduces costs for intermittent workloads, freeing you from the need to manage idle GPU hardware.
Cost Optimization for Workloads
You gain full control over your budget, reducing costs compared to fixed monthly plans by only paying when your workloads are actually running.
Predictable Costs
Transparent hourly pricing, with no hidden fees & zero-cost egress.
Unleash throughput for high-resolution media
From cinematic rendering to high-volume video transcoding, UpCloud’s NVIDIA GPUs deliver the performance required for complex media tasks.

Dedicated GPU power
Leverage the dedicated GPU power for high-resolution rendering and transcoding, ensuring your projects run smoothly and efficiently.

Reliable performance without compromise
Our service is built on enterprise-grade infrastructure with redundancy at every level, delivering consistent performance and reliability for your video processing and 3D rendering needs. Focus on your creative work while we ensure your GPU resources are always available.

Audio Processing
Remove noise, normalize loudness, encode to AAC or Opus, split dialogue and music when needed, GPU where it helps, CPU for the rest, & optional ASR or TTS for transcripts and dubs.
Dedicated GPU power
Leverage the dedicated GPU power for high-resolution rendering and transcoding, ensuring your projects run smoothly and efficiently.
Reliable performance without compromise
Our service is built on enterprise-grade infrastructure with redundancy at every level, delivering consistent performance and reliability for your video processing and 3D rendering needs. Focus on your creative work while we ensure your GPU resources are always available.
Audio Processing
Remove noise, normalize loudness, encode to AAC or Opus, split dialogue and music when needed, GPU where it helps, CPU for the rest, & optional ASR or TTS for transcripts and dubs.
GPU Server Hardware
NVIDIA L4

Cost-effective AI Inference, High-throughput Video Processing, and Edge AI deployments. Optimized for low-latency, energy-efficient operations.
The NVIDIA L4 Tensor Core GPU powered by the NVIDIA Ada Lovelace architecture delivers universal, energy-efficient acceleration for video, AI, visual computing, graphics, virtualization, and more.
NVIDIA L40S
Generative AI, Mid-to-Large Scale AI Model Training and Inference, Real-time 3D Rendering, Virtual Production, and High-Performance Computing (HPC) simulations.
The NVIDIA L40S GPU is the most powerful universal GPU for the cloud, delivering end-to-end acceleration for the next generation of AI-enabled applications.
NVIDIA RTX PRO 6000 Blackwell Server

Agentic and Generative AI, LLM Inference, AI-Driven Rendering, 3D Graphics, Video Processing, Scientific Computing, and Data Analytics.
The NVIDIA RTX PRO 6000 Blackwell Server Edition delivers powerful AI and visual computing performance for demanding enterprise workloads. Powered by the NVIDIA Blackwell architecture and equipped with 96 GB of GDDR7 memory, it accelerates complex AI models, photorealistic rendering, simulations, and data-intensive workflows.
NVIDIA H100 SXM

The NVIDIA H100 SXM GPU delivers exceptional performance, scalability, and security for every workload. H100 uses breakthrough innovations based on the NVIDIA Hopper™ architecture to deliver industry-leading conversational AI, speeding up large language models (LLMs) by 30X.
H100 also includes a dedicated Transformer Engine to solve trillion-parameter language models.
NVIDIA B200 SXM

Generative AI, Large-Scale AI Model Training and Inference (LLMs), High-Performance Computing (HPC) simulations, Scientific Computing, and Data Analytics.
The NVIDIA B200 SXM GPU, powered by the Blackwell architecture, is the world’s most powerful AI chip, designed to power a new era of computing with up to 4x faster training and 30x faster inference than previous generations.
NVIDIA B300 SXM

Advanced AI Reasoning, Large-Scale AI Model Training and Inference, Agentic and Multimodal AI, High-Performance Computing (HPC), Scientific Computing, and AI Factory deployments.
The NVIDIA B300 SXM GPU, powered by the Blackwell Ultra architecture, is designed for the next generation of AI reasoning and large-scale accelerated computing. With up to 288 GB of HBM3e memory and 8 TB/s of memory bandwidth, B300 delivers 1.5x greater dense FP4 performance and 2x higher attention performance than B200, accelerating long-context models, complex inference, and training at data-center scale.

Introducing GPU Spot Instances
Get up to 25% off selected GPUs
Spot instances run on our spare capacity. If that capacity is needed elsewhere in our network, the instance will be terminated. But if your workloads are stateless, fault-tolerant, or can easily pause and resume, you’re getting top-tier GPU performance at a massive discount.
GPU Server configurations
Configurations
GPU Servers with NVIDIA L4
GPUs
1 – 3 per server
CPU cores
8 – 32
Memory
64 – 384 GB
- Premium AMD CPUs
- Up to 100k IOPS with MaxIOPS
- Choice of Block Storage
- 1000 Mbps networking
- Zero egress fees
- 99.999% SLA
Starting from
€0.57/hour
| GPU | CPU cores | RAM | Spot Price | Price |
|---|---|---|---|---|
| 1 x NVIDIA L4 | 8 cores | 64 GB | €0.57/h | €0.58/h |
| 1 x NVIDIA L4 | 12 cores | 128 GB | €0.69/h | €0.70/h |
| 1 x NVIDIA L4 | 16 cores | 192 GB | €0.81/h | €0.82/h |
| 1 x NVIDIA L4 | 20 cores | 256 GB | €0.93/h | €0.94/h |
| 2 x NVIDIA L4 | 12 cores | 128 GB | €1.17/h | €1.18/h |
| 2 x NVIDIA L4 | 16 cores | 192 GB | €1.29/h | €1.30/h |
| 2 x NVIDIA L4 | 20 cores | 256 GB | €1.41/h | €1.42/h |
| 2 x NVIDIA L4 | 32 cores | 384 GB | €1.63/h | €1.64/h |
| 3 x NVIDIA L4 | 16 cores | 192 GB | €1.79/h | €1.80/h |
| 3 x NVIDIA L4 | 20 cores | 256 GB | €1.91/h | €1.92/h |
| 3 x NVIDIA L4 | 32 cores | 384 GB | €2.13/h | €2.14/h |
GPU Servers with NVIDIA L40S
GPUs
1 – 3 per server
CPU cores
8 – 32
Memory
64 – 384 GB
- Premium AMD CPUs
- Up to 100k IOPS with MaxIOPS
- Choice of Block Storage
- 1000 Mbps networking
- Zero egress fees
- 99.999% SLA
Starting from
€0.83/hour
| GPU | CPU cores | RAM | Spot Price | Price |
|---|---|---|---|---|
| 1 x NVIDIA L40S | 8 cores | 64 GB | €0.83/h | €1.11/h |
| 1 x NVIDIA L40S | 12 cores | 128 GB | €0.94/h | €1.25/h |
| 1 x NVIDIA L40S | 16 cores | 192 GB | €1.15/h | €1.53/h |
| 1 x NVIDIA L40S | 20 cores | 256 GB | €1.35/h | €1.81/h |
| 2 x NVIDIA L40S | 12 cores | 128 GB | €1.56/h | €2.08/h |
| 2 x NVIDIA L40S | 16 cores | 192 GB | €1.98/h | €2.64/h |
| 2 x NVIDIA L40S | 20 cores | 256 GB | €2.40/h | €3.19/h |
| 2 x NVIDIA L40S | 32 cores | 384 GB | €2.81/h | €3.75/h |
| 3 x NVIDIA L40S | 16 cores | 192 GB | €2.81/h | €3.75/h |
| 3 x NVIDIA L40S | 20 cores | 256 GB | €3.23/h | €4.31/h |
| 3 x NVIDIA L40S | 32 cores | 384 GB | €3.65/h | €4.86/h |
GPU Servers with NVIDIA RTX PRO 6000
GPUs
1 – 8 per server
CPU cores
12 – 96
Memory
240 – 1920 GB
- Premium AMD CPUs
- Up to 100k IOPS with MaxIOPS
- Choice of Block Storage
- 1000 Mbps networking
- Zero egress fees
- 99.999% SLA
Starting from
€0.87/hour
| GPU | CPU cores | RAM | Spot Price | Price |
|---|---|---|---|---|
| 1 x NVIDIA RTX PRO 6000 | 16 cores | 80 GB | €0.87/h | €1.65/h |
| 2 x NVIDIA RTX PRO 6000 | 32 cores | 160 GB | €1.74/h | €3.30/h |
| 4 x NVIDIA RTX PRO 6000 | 64 cores | 320 GB | €3.48/h | €6.60/h |
| 8 x NVIDIA RTX PRO 6000 | 128 cores | 640 GB | €6.96/h | €13.20/h |
GPU Servers with NVIDIA H100 SXM
GPUs
1 – 8 per server
CPU cores
12 – 96
Memory
240 – 1920 GB
- Premium Intel CPUs
- Up to 100k IOPS with MaxIOPS
- Choice of Block Storage
- 1000 Mbps networking
- Zero egress fees
- 99.999% SLA
Starting from
€1.78/hour
| GPU | CPU cores | RAM | Spot Price | Price |
|---|---|---|---|---|
| 1 x NVIDIA H100 | 12 cores | 240 GB | €1.79/h | €2.17/h |
| 2 x NVIDIA H100 | 24 cores | 480 GB | €3.58/h | €4.34/h |
| 4 x NVIDIA H100 | 48 cores | 960 GB | €7.16/h | €8.68/h |
| 8 x NVIDIA H100 | 96 cores | 1920 GB | €14.32/h | €17.36/h |
GPU Servers with NVIDIA B200 SXM
GPUs
1 – 8 per server
CPU cores
12 – 96
Memory
240 – 1920 GB
- Premium Intel CPUs
- Up to 100k IOPS with MaxIOPS
- Choice of Block Storage
- 1000 Mbps networking
- Zero egress fees
- 99.999% SLA
Starting from
€3.38/hour
| GPU | CPU cores | RAM | Spot Price | Price |
|---|---|---|---|---|
| 1 x NVIDIA B200 | 24 cores | 240 GB | €3.68/h | €5.26/h |
| 2 x NVIDIA B200 | 48 cores | 480 GB | €7.36/h | €10.52/h |
| 4 x NVIDIA B200 | 96 cores | 960 GB | €14.73/h | €21.04/h |
| 8 x NVIDIA B200 | 192 cores | 1920 GB | €29.46/h | €42.08/h |
GPU Servers with NVIDIA B300 SXM
GPUs
1 – 8 per server
CPU cores
28 – 224
Memory
240 – 1920 GB
- Premium Intel CPUs
- Up to 100k IOPS with MaxIOPS
- Choice of Block Storage
- 1000 Mbps networking
- Zero egress fees
- 99.999% SLA
Starting from
€5.21/hour
| GPU | CPU cores | RAM | Spot Price | Price |
|---|---|---|---|---|
| 1 x NVIDIA B300 | 28 cores | 240 GB | €5.21/h | €6.95/h |
| 2 x NVIDIA B300 | 56 cores | 480 GB | €10.43/h | €13.90/h |
| 4 x NVIDIA B300 | 112 cores | 960 GB | €20.85/h | €27.80/h |
| 8 x NVIDIA B300 | 224 cores | 1920 GB | €41.70/h | €55.60/h |
Scale on-demand, without limits
Media projects often have fluctuating demands. Our flexible Cloud GPU server plans allow you to scale your resources instantly to match your project’s needs.

Accessible & flexible
Start immediately without upfront commitments or complex contracts & spin up GPU resources precisely when you need them.

Scales with project load
Easily scale your GPU resources up or down based on actual demand, making it perfect for studios and creative teams looking to optimize their infrastructure costs and adapt to changing project requirements.

Zero lock-in
Benefit from instant start capabilities and freedom from fixed billing. Many providers still require fixed-month billing or pre-allocated GPU blocks, but UpCloud is built for agile development and dynamic project cycles.
Accessible & flexible
Start immediately without upfront commitments or complex contracts & spin up GPU resources precisely when you need them.
Scales with project load
Easily scale your GPU resources up or down based on actual demand, making it perfect for studios and creative teams looking to optimize their infrastructure costs and adapt to changing project requirements.
Zero lock-in
Benefit from instant start capabilities and freedom from fixed billing. Many providers still require fixed-month billing or pre-allocated GPU blocks, but UpCloud is built for agile development and dynamic project cycles.
Compare GPU models
GPU Model Specifications
UpCloud GPU Servers offer a range of GPU models with the unique ability to scale the server and GPUs as needed.
Start with a smaller card for development purposes, then migrate to use more powerful cards for production use, or vice-versa, all without needing to reinstalling the server or losing any data.
It’s as easy as shutting down the server, changing the plan and powering the server back up again!
| NVIDIA L4 | NVIDIA L40S | NVIDIA RTX PRO 6000 Blackwell Server Edition | NVIDIA H100 | NVIDIA B200 | NVIDIA B300 | |
|---|---|---|---|---|---|---|
| Primary use case | Energy-efficient accelerator for AI inference, video transcoding, graphics/VDI and edge deployments |
Multi-workload “universal” GPU – GenAI, LLM training & inference, 3D graphics, rendering, video |
Agentic and generative AI, 3D rendering, visual computing, video processing, scientific computing and data analytics |
High-traffic inference, massive batch processing and large-model training |
Trillion-parameter model inference, model training, running complex models in real-time |
Advanced AI reasoning, large-scale model training and inference, agentic and multimodal AI, HPC and AI factory workloads |
| Architecture | Ada Lovelace | Ada Lovelace | Blackwell | Hopper | Blackwell | Blackwell Ultra |
| GPU Memory | 24GB GDDR6 | 48GB GDDR6 | 96GB GDDR7 | 80GB HBM3e | 180GB HBM3e | 288GB HBM3e |
| Memory Bandwidth | 300GB/s | 864GB/s | 1.6TB/s | 3.35TB/s | 8.0TB/s | 8.0TB/s |
| Peak compute | FP32 30.3 TFLOPS FP8 Tensor 0.48 PFLOPS |
FP32 91.6 TFLOPS FP8 Tensor 1.46 PFLOPS |
FP32 120 TFLOPS FP8 Tensor 2.00 PFLOPS |
FP32 67 TFLOPS FP8 Tensor 3.90 PFLOPS |
FP32 74.45 TFLOPS FP8 Tensor 9.00 PFLOPS |
FP8 Tensor 9.00 PFLOPS FP4 Tensor 18.00 PFLOPS |
Save on your monthly bills with Zero-cost egress
Forget unpredictable network bills at the end of the month. With zero-cost egress, you’ll never see a surprise bill for transfer usage.
Never pay for network transfer, even when you scale up, you can redirect savings towards accelerating your business growth.
Build your complete media production stack
Seamlessly integrate GPU power with our high-performance ecosystem to create a robust and efficient workflow for your media projects.
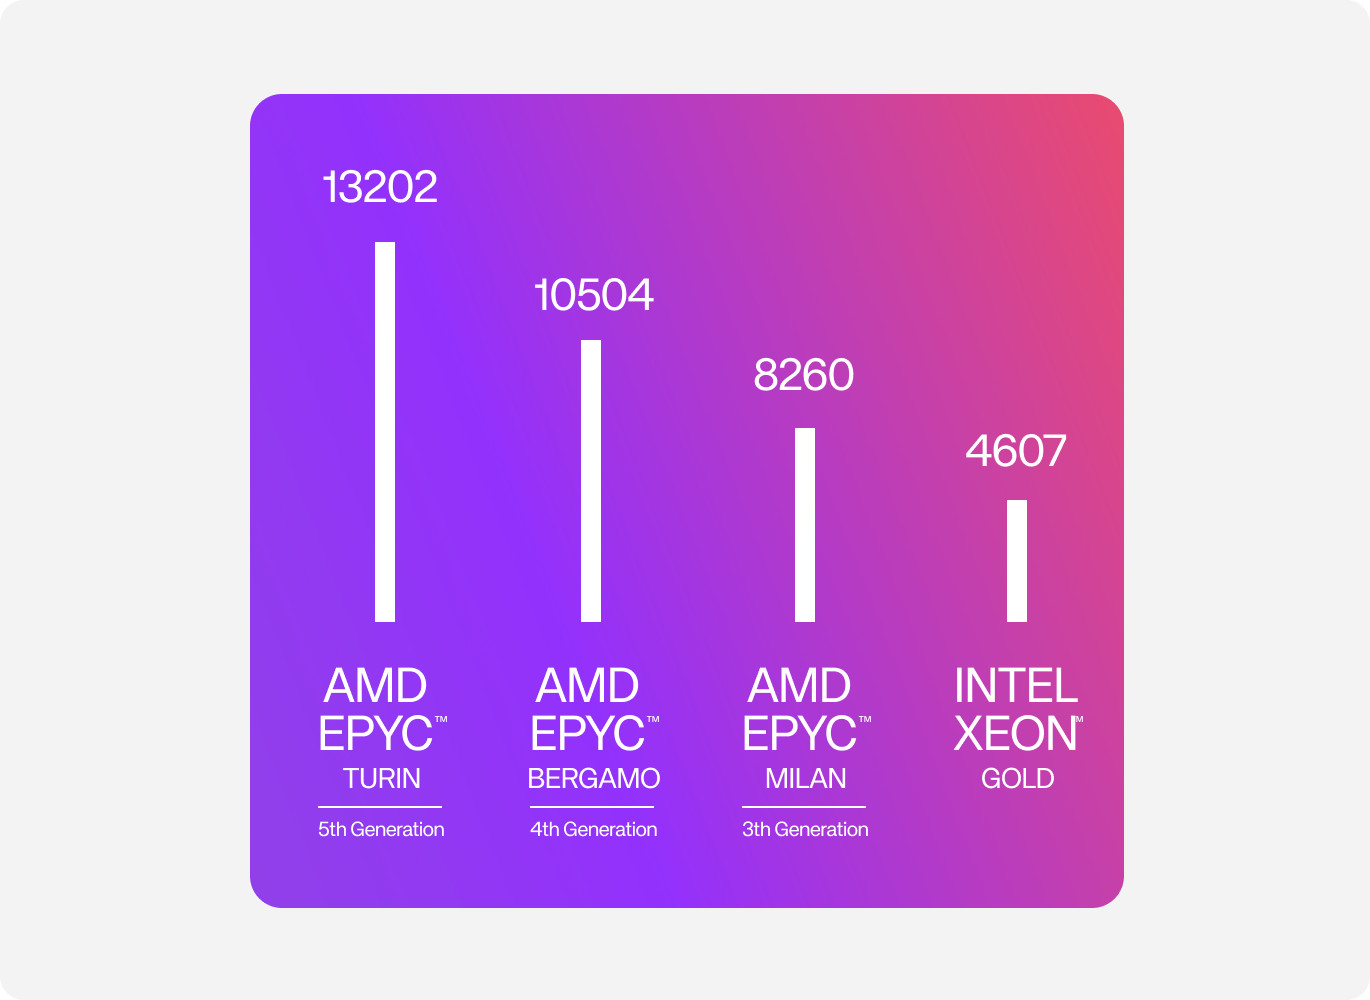
Powerful compute with AMD EPYC Servers
You can’t have GPUs without a server. Combine GPU servers with our state-of-the-art, high-performance AMD EPYC hardware cloud servers for a complete, balanced architecture. Conquer massive parallel jobs and general tasks without compromise in a single architecture.

High-speed Object Storage for assets
Fuel your workloads with our high-speed Object Storage. It’s ideal for storing large video files, 3D assets, and other immutable data. Designed for massive datasets, it ensures your servers remain productive with stateless and concurrent access from any number of hosts, and built-in object versioning.
Powerful compute with AMD EPYC Servers
You can’t have GPUs without a server. Combine GPU servers with our state-of-the-art, high-performance AMD EPYC hardware cloud servers for a complete, balanced architecture. Conquer massive parallel jobs and general tasks without compromise in a single architecture.
High-speed Object Storage for assets
Fuel your workloads with our high-speed Object Storage. It’s ideal for storing large video files, 3D assets, and other immutable data. Designed for massive datasets, it ensures your servers remain productive with stateless and concurrent access from any number of hosts, and built-in object versioning.
Sustainable media processing
Innovate responsibly. Our Helsinki data center routes excess heat generated from our GPUs directly into the city’s district heating network. This makes our GPU offering in Helsinki one of the most environmentally friendly options on the market, contributing to a greener future while powering your creative endeavors.
Our Helsinki data center is powered by 100% renewables and routes excess heat generated from our GPUs into the city’s district heating network. This makes our GPU offering in Helsinki one of the most environmentally friendly options on the market, contributing to a greener future while powering your AI.
Ready to accelerate your rendering and transcoding?
Gain powerful, cost-effective GPU computing for your media projects today.
GPU FAQ
Frequently asked questions
A GPU server is a cloud server equipped with a dedicated graphics processing unit alongside its CPU, memory and storage. While originally designed for rendering graphics, GPUs excel at parallel processing, performing thousands of calculations simultaneously. This makes them well suited to workloads like AI model training, machine learning inference, video transcoding and scientific computing, where the same operation runs across huge amounts of data at once.
A regular cloud server relies on CPUs, which handle a wide range of tasks sequentially and are ideal for general workloads like web hosting, databases and applications. A GPU server adds a graphics processor with thousands of smaller cores built for parallel work. For tasks like training neural networks or processing video, a GPU can be orders of magnitude faster than a CPU alone. Many teams run both, using Cloud Servers for their applications and GPU Servers for compute-heavy jobs, connected over the same private network.
Common uses include training and fine-tuning machine learning models, running inference for AI applications like chatbots and recommendation engines, video transcoding and streaming, 3D rendering, and scientific simulations. Generative AI has driven much of the recent demand, from serving large language models to image and video generation. See our AI/ML solutions and Audio/Video solutions pages for detail on specific workloads.A
For small models and light experimentation, a CPU can be enough. But for training models of any real size, or serving inference at production speed, a GPU is effectively essential. Even running open-weight models like Llama or Mistral locally becomes impractical on CPU beyond the smallest sizes. A single L4 or L40S server is a sensible starting point for most inference workloads, and you can scale up from there. Our Ollama tutorial shows how to get a model running in under an hour.
Yes. GPU Servers are billed hourly with no long-term commitment, so you can spin one up for a training run and delete it when finished. For maximum savings on interruptible workloads, spot pricing offers the same hardware at a significant discount. Monthly costs are capped at 28 days of usage, so a server running all month never costs more than the listed monthly price.
It depends on the workload. The NVIDIA L4 is the most cost-effective option for AI inference, video transcoding and edge deployments. The L40S is a versatile all-rounder suited to generative AI, mid-scale model training and 3D rendering. The H100 handles high-traffic inference and large model training, while the B200 is built for the largest jobs, including trillion-parameter models. You can also switch between GPU models later by shutting down the server and changing the plan, so you are not locked into your first choice.
For more guidance, see our AI/ML GPU solutions and Audio/Video GPU solutions pages.
All GPU Server plans run in our data center in Helsinki, Finland. The facility is powered entirely by renewable energy and recovers up to 90% of waste heat, which is fed into Helsinki’s district heating network. Read more about our approach on the EU Sovereign Cloud page or explore our data centers.
GPU Servers deploy in just a few minutes through the control panel or API. Our AI/ML-ready Ubuntu template comes with NVIDIA drivers and tooling pre-installed, so you can go from deployment to running workloads without manual setup. If you want a practical walkthrough, our tutorial on running LLMs with Ollama takes you from a fresh server to inference on an open-weight model.
GPU Servers can be attached to your infrastructure alongside our other products and connected over SDN private networks. If you are orchestrating containerised workloads, see Managed Kubernetes for running clusters alongside your GPU capacity.
By using our AI/ML-ready GPU Ubuntu template, the necessary NVIDIA drivers are pre-installed. If you choose another operating system, you will need to manually install the appropriate NVIDIA drivers and CUDA toolkit to enable GPU functionality.Q
No. All GPU Server plans include zero-cost egress, so there are no charges for outbound data transfer. This matters for AI workloads where moving datasets, model weights and inference results in and out of the cloud can otherwise become a significant cost.
Our Fair Transfer Policy applies.
Multi-GPU servers are equipped with more than one dedicated GPU. All GPUs are exposed to your server via PCIe passthrough, allowing you to utilize them for parallel processing, distributed training, or other multi-GPU workloads. You can verify the available GPUs using the nvidia-smi tool.
Yes, each GPU is dedicated to a single server and is not shared with other customers. This ensures consistent performance and security for your workloads.
Our advice is to match the GPU to the job. You can find a great comparison between our GPUs >here<
- For inference on small to mid-sized models, the L4 offers the best price to performance.
- The L40S steps up to generative AI, fine-tuning and mid-scale training.
- The H100 suits large model training and high-throughput inference
- The B200 is for the most demanding jobs, including training and serving the largest models.
Memory is usually the deciding factor: your model weights, plus overhead, need to fit in GPU memory for inference, and training needs considerably more. If in doubt, start smaller. You can shut down and switch to a bigger GPU without reinstalling.
Beyond the GPU itself, consider how you deploy it. GPU Servers on hourly billing suit most teams, Managed Kubernetes works for containerised workloads across multiple nodes, and Private Cloud GPUs provide dedicated hardware for organisations with strict compliance or isolation requirements.
If you are unsure, start with a single GPU Server and contact our sales team.
GPU Server plans are only billed when the server is powered on.
However, attached block storages and public IPv4 addresses are reserved and thus billed even when the server is shut down.
Spot pricing is good for time-insensitive workloads, sold at a discount. A spot instance may be terminated at any given time. Read more at GPU Server Spot pricing documentation.
GPU virtualization is how a physical GPU is made available to virtual servers. There are two main approaches. Shared virtualization splits one GPU between multiple customers, which lowers cost but means unpredictable performance. Passthrough gives a virtual server direct, exclusive access to the physical GPU. UpCloud GPU Servers use passthrough, so the full performance of the GPU is yours alone, with no sharing and no contention from other tenants. You get bare-metal GPU performance combined with the flexibility of a cloud server.
Yes. If you need isolated infrastructure for compliance or security reasons, Private Cloud GPUs provide dedicated GPU hardware within your own private cloud environment. This suits organisations with strict data handling requirements, including public sector and regulated industries.